By Lucas Malaspina
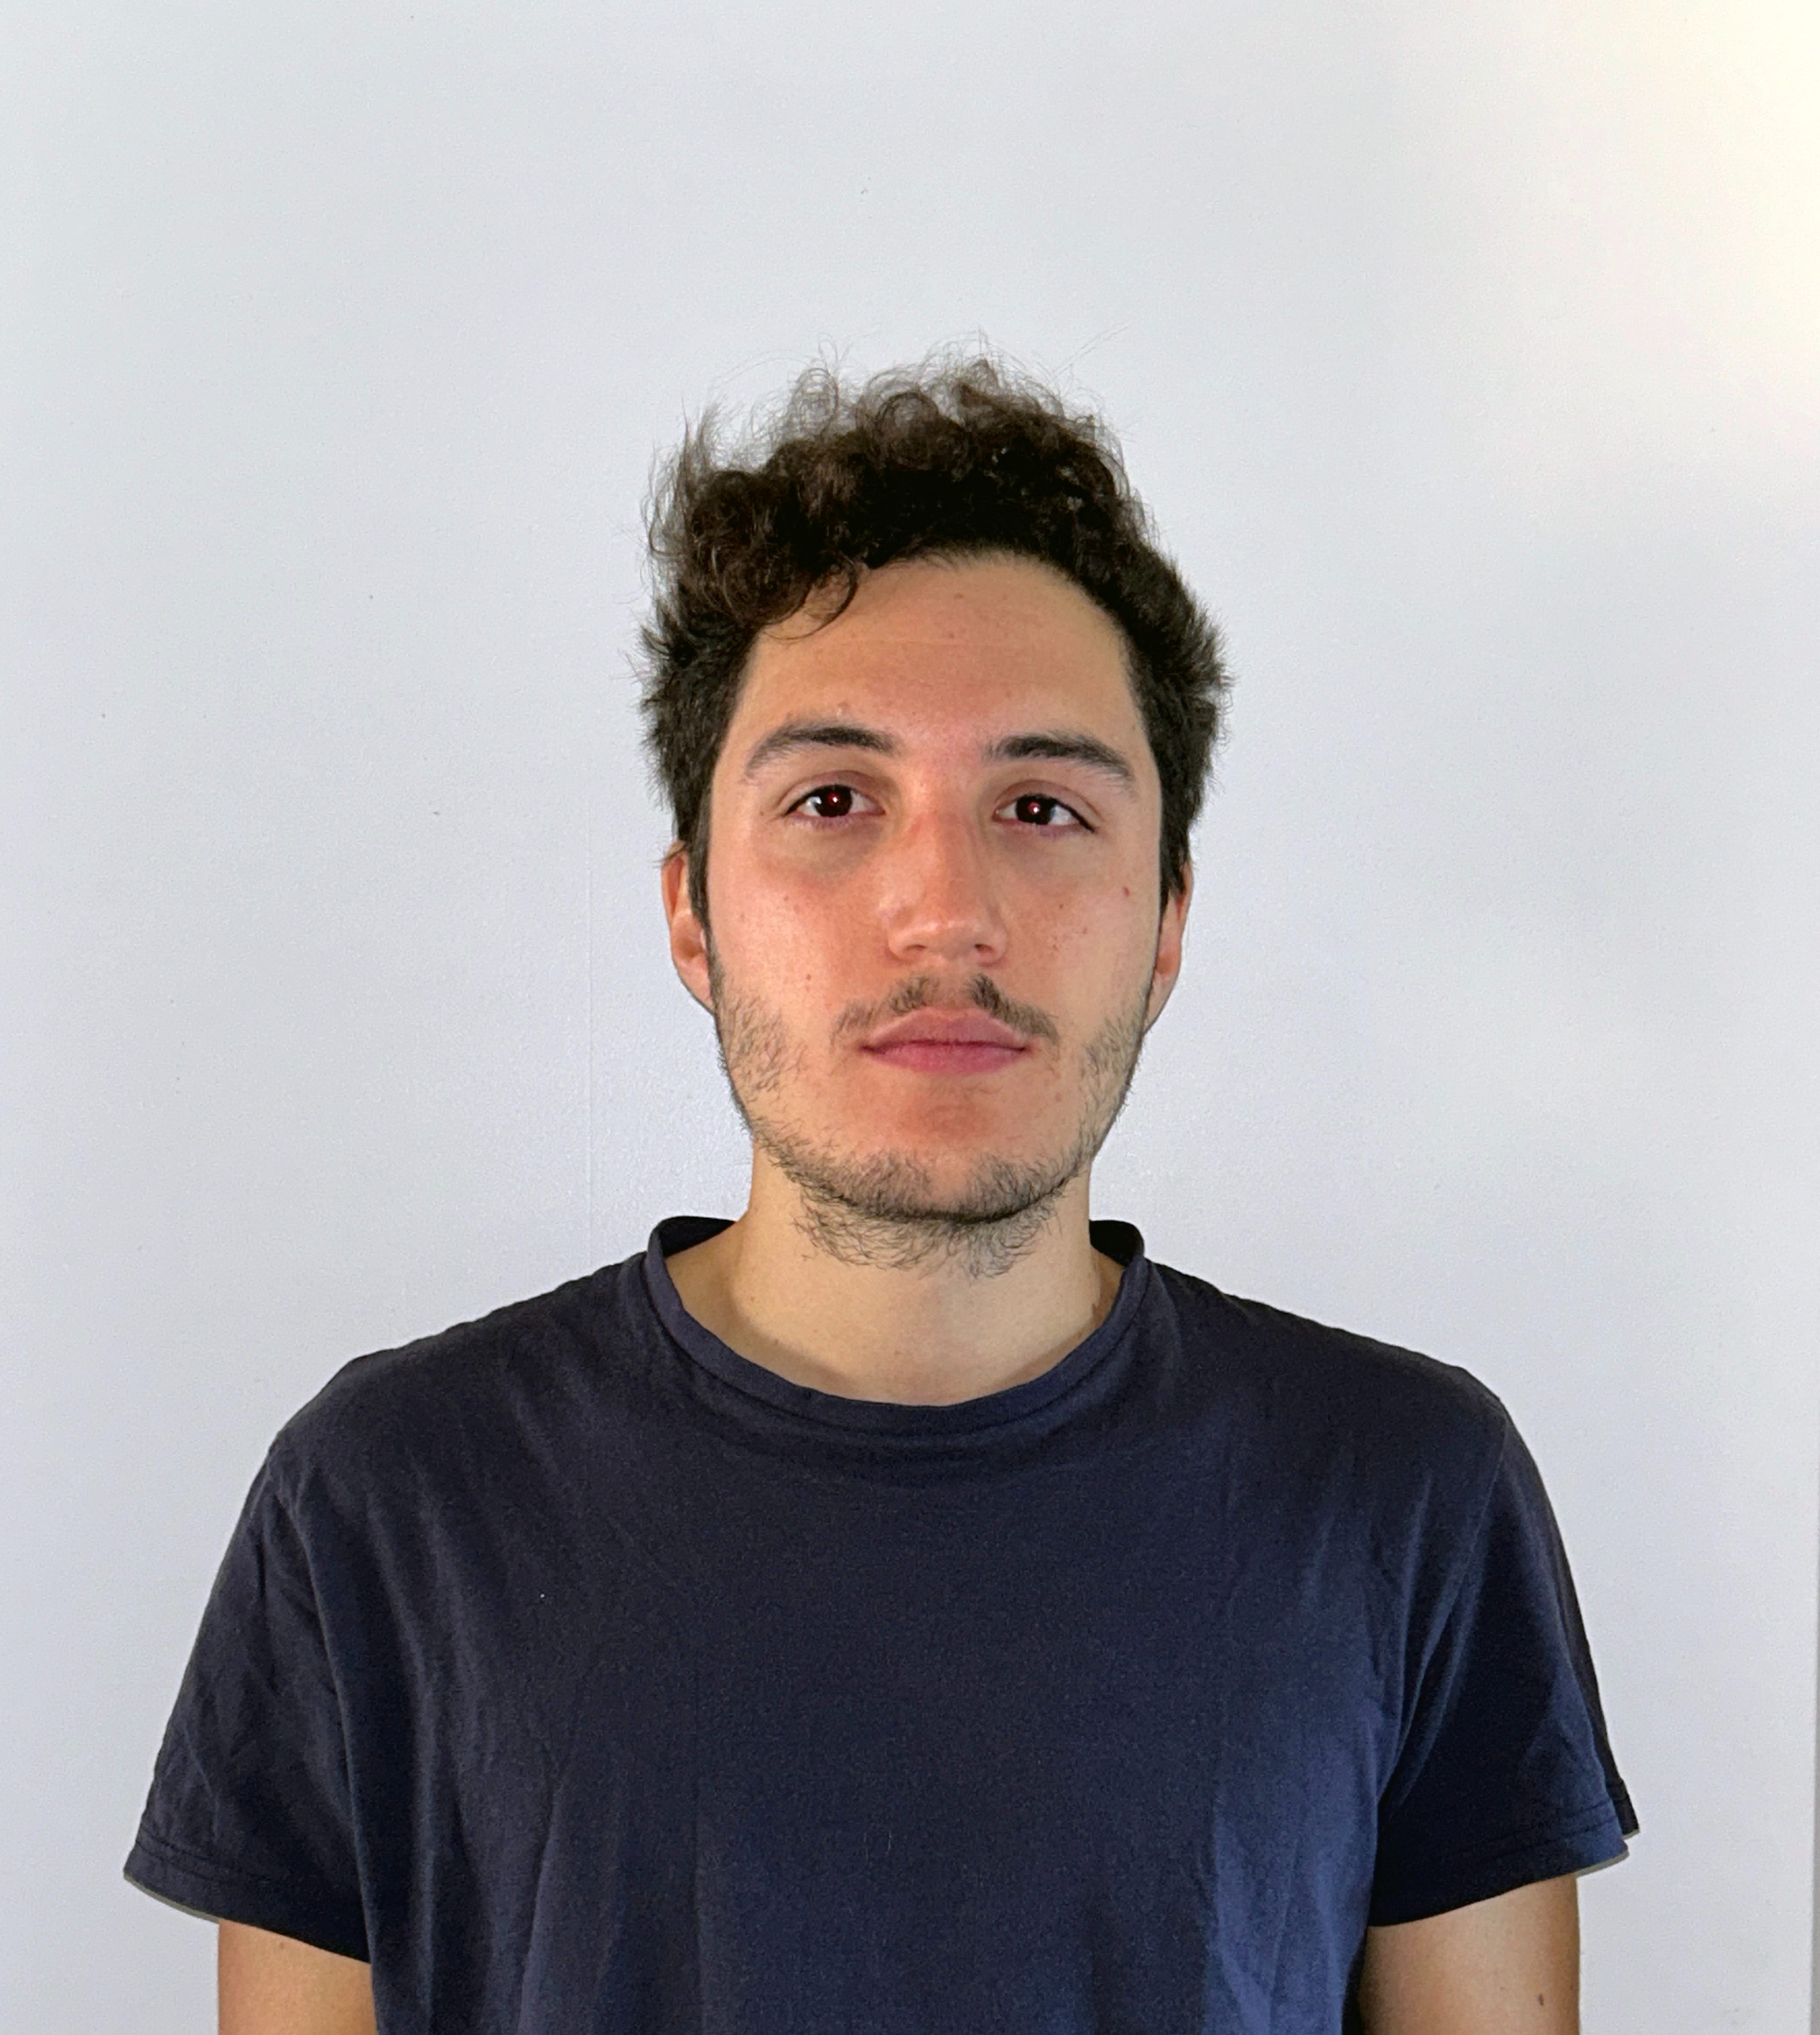
Artificial intelligence is advancing relentlessly, transforming the world of work and impacting society and politics on a global scale. Mauro Giordano is an Argentine tech entrepreneur who takes pride in Argentina’s public education system. From his early days at the University of Buenos Aires to the creation of DigoDat alongside his friend Alan Daitch and his experience at Media Monks—a leading multinational advertising agency—Giordano has always been interested in automation, software engineering, and artificial intelligence. He is currently finishing his thesis in Computer Science. We spoke with Mauro about the history of AI and its possible futures.
DigoDat was a company that managed to establish itself in the world of data analytics at a time when this field was beginning to gain importance, even though its significance wasn’t yet apparent to most people. After selling the company, he joined Media Monks as SVP of Data, where Mauro Giordano led a team of more than 200 people. He is currently on a sabbatical, exploring new projects.
How did you decide to get into computer science?
The truth is, I’ve been interested in computers since I was a kid. I was lucky enough to have a computer at home and also at my grandparents’ house. In fact, that’s where I first used broadband—and where I also started chatting and using the internet during that golden, nostalgic era of the late ’90s. The internet was very different from what it is today, and that’s how I got into programming and technology. When I had to decide what to study, I considered literature or even philosophy, but I wasn’t doing so well in math, and I felt that if I pursued a degree in a hard science, like computer science, it might help me improve in that area. So I chose a major that would challenge me and force me to overcome those difficulties, while still allowing me to read on my own about the topics I enjoyed.
I recently finished a book, “Mindset” by the American psychologist Carol Dweck. It discusses the growth mindset versus the fixed mindset. In short, it argues that people who face difficulties strive to learn and improve, while others believe they aren’t good at something and give up. What strikes me as remarkable about your story is that, even though you didn’t get along well with math, you decided to study computer science precisely because of that.
Yes, that’s exactly how it was. At the time, I thought a typical college degree took about five years, which is a long time—especially at age 18, when that’s almost a quarter of your life. I was frustrated that I wasn’t good at math, because I really struggled with it. So I figured that if I pursued this major, I could improve. It was quite a struggle; I had my ups and downs, but in the end, I improved a lot. It was a good decision. What continues to surprise me today is that, despite the pervasive role of technology in our lives, majors like engineering or computer science still struggle to attract students compared to more traditional fields. I find that an interesting phenomenon to explore.
Right now at the University of Buenos Aires, there’s a sharp decline in all the humanities programs, and I think it’s related to this. Critical thinking is very interesting and contributes a lot, but that alone isn’t enough. I recently saw a video on Instagram of a student leader who said, “We have to do something, because otherwise, all the kids are going to have to keep going to CoderHouse to learn what they could learn in the School of Social Sciences.”
That’s an interesting point. It’s not that you need a college degree in programming or computer science, but I think it would be beneficial to integrate those skills into education starting at earlier levels, such as primary or secondary school. For me, these days, programming is just as important as knowing how to read and write. You don’t need to be an expert programmer, but you do need to view programming as a tool for thinking and solving problems. There are efforts in that direction, such as the Sadosky Foundation’s program, but I think there’s still a long way to go.
Some might ask: What’s the point of programming if we now have tools like ChatGPT that do the programming for us? We can talk about that later, but I believe it remains a crucial skill that will make a difference in the future in terms of employability and competitiveness.
Before we get into that, could you tell us a little about your experience at DigoDat? After starting college, you launched this project, which you ran for many years. How did you become a Google partner and start working with large companies?
DigoDat’s story began along two separate paths. I became very interested in data while I was in college. In 2012, for example, Coursera was just launching, and one of the first courses was on machine learning, which really opened my eyes to what could be done with data. My partner, Alan Daitch, came from the world of digital marketing and saw an opportunity to use data to improve business decision-making. In 2015, when I was 24, we started DigoDat with the goal of helping companies work with their data, primarily focusing on digital marketing.
We relied heavily on Google Analytics to collect and analyze data from websites and mobile apps. Back then, advertising agencies were excellent at digital marketing and campaign execution, but they fell short on the technical side of data. That’s where we saw an opportunity to focus on what we knew how to do. Also, one of our biggest successes was how we built the team. Alan came from the world of economics and had strong ties to the School of Economic Sciences, so we recruited many economists who had excellent data analysis skills. Plus, Alan was very active in student activism at the school at the time. So, we surrounded ourselves with many activists who already had strong interpersonal skills when it came to negotiating and talking with clients—they were very young, but they performed exceptionally well in meetings, presentations, interactions, and so on. I think that combination of all those skills allowed us to build a rock-solid team, and fortunately, that began to pay off. And well, that’s how it all started in 2015—I’d say it really took off around 2017.
We started in Argentina, but then expanded to other countries, such as Mexico, Colombia, Peru, and Chile. That expansion allowed us to see that we could compete in more advanced markets, and in the end, we realized that the technical work was quite similar everywhere.
You started in Argentina and then grew to become one of Google’s leading analytics partners in Latin America. What was that expansion experience like?
It was very interesting. When we started out, right at the beginning, we said, “Let’s start in Argentina because that’s where we are.” But we never thought about going out to sell in Europe or the United States, because we felt those were more advanced markets and we saw ourselves as inferior. But after expanding throughout Latin America, we realized that the technical work was more or less the same everywhere. And that made us see that we could compete in those markets as well.
After going through a merger with a global corporation and gaining exposure to those primary markets, I can tell you today that it was wrong to think we couldn’t compete technically in the United States or Europe. In fact, Argentine talent is spectacular, and that’s due, in large part, to the public education system.
Now, I’d like to ask you about the current state of artificial intelligence. There’s a lot of buzz around the topic, but what’s really going on?
These days, the term “artificial intelligence” is everywhere. You go to any company’s website and see that they claim to use artificial intelligence for everything. But I think that, to understand where we stand, we need to take a step back and look at where all of this comes from. The concept of artificial intelligence emerged at a 1956 conference in Dartmouth, where several scientists gathered with the idea that any aspect of human learning or intelligence could be described precisely enough to be simulated by a machine.
One of the most important milestones in the history of artificial intelligence was the Turing Test, proposed by Alan Turing in 1950. This test posits that if a machine can hold a conversation with a human without the human realizing they are talking to a machine, then that machine can be considered “intelligent.” At the time, the Turing Test was revolutionary. Today, with technologies like ChatGPT, we can say that many machines would pass this test, but that does not necessarily mean they are “intelligent” in the sense that we understand it.
In the 1970s, there was a period known as the “AI winter,” because expectations were too high and no significant progress was made. But in recent years, thanks to advances in neural networks and deep learning, we’ve seen a renaissance in this field. Technologies like ChatGPT or language models such as Google’s have made impressive strides in the ability to generate coherent and convincing text.
You recently mentioned the example of “Nazis of different ethnicities” generated by artificial intelligence. What happened with that?
Yes, that was something that caused quite a bit of controversy. What happened was that some people asked an AI model (Google’s Gemini) to generate images of Nazis, and the AI generated images of Nazis of different ethnicities, which makes no historical sense. This drew a lot of criticism because it seemed like an attempt to be politically correct in terms of ethnic representation, but it ended up being a serious mistake. AI doesn’t have a real understanding of context; it’s just generating images based on the data it’s been trained on, and in this case, it did something completely out of place. These kinds of errors show us that artificial intelligence can’t always replace human judgment and that we need to be careful about the information we feed it.
I’m interested in how prosumers have contributed to the development of artificial intelligence. How did that work?
Much of the progress in artificial intelligence has been achieved thanks to the participation of users who, without knowing it, have been training the algorithms. A good example is tagging people on Facebook. When you uploaded a photo and the platform suggested tagging your friends, you were helping to train a facial recognition model. Facebook used the tags to learn how to identify faces, and as more users tagged people, the model improved.
Another example is the use of CAPTCHAs. Do you remember those distorted images of text that you had to type to prove you weren’t a robot? What many people don’t know is that, in addition to verifying that you were human, those CAPTCHAs were also used to train optical character recognition (OCR) systems. Google, for example, used those images to digitize old books and documents. When a CAPTCHA showed you two words, one was a control word, but the other was part of a scanned book that the AI couldn’t recognize, and by typing it correctly, you were helping to digitize that content. So, in reality, we were all working for free to improve these systems without even realizing it.
So we were all little contributors without even knowing it. And now all of that is feeding these massive artificial intelligence systems.
Exactly. This raises important questions about the use of our data and how it’s being leveraged to train these technologies. That’s why the debate over privacy and data usage remains highly relevant. The services we think are free—we’re actually paying for them with our information.
I completely agree. You also mentioned earlier some concerns about data use with tools like World Coin, which scans irises. What are your thoughts on that?
Yes, World Coin is a project led by Sam Altman, one of the founders of OpenAI, which has also generated quite a bit of controversy. The idea behind World Coin is to create a kind of universal identity based on iris scanning, which would serve as proof of humanity in the future—especially in a world where artificial intelligence is capable of impersonating visual and verbal identities. It’s an interesting topic, but also a problematic one. Iris scanners create a unique biometric signature, and if that information is compromised, it’s not something you can change like a password. I think it’s risky, especially if it isn’t properly regulated. They were offering people cryptocurrency in exchange for scanning their irises, which also raises ethical questions.
It’s no surprise that there are both optimistic and pessimistic views on artificial intelligence. You mentioned to me privately Eliezer Yudkowsky, who has a rather apocalyptic view of the future of AI.
Yes, Eliezer Yudkowsky is a researcher who focuses on the safety of artificial intelligence and on what’s called “AI alignment”—that is, how to ensure that AI systems pursue goals aligned with human well-being. In an open letter he published in Time, he warned that we should not only pause progress in AI for six months, as some have suggested, but that we should halt it entirely. His argument is that we don’t know what might happen if we develop a superintelligence that is beyond our control. He has a very apocalyptic view, believing that AI could pose an existential threat to humanity if it isn’t properly regulated.
On the other hand, you have people like Yann LeCun, who is the head of artificial intelligence at Meta, who is much more optimistic. He argues that artificial intelligence won’t bring about such a drastic leap forward overnight, but rather that progress will be gradual. He also argues that AI alignment and safety will be inherent in the systems that are designed, because if they weren’t, they wouldn’t be useful or practical. So, while Yudkowsky suggests an almost apocalyptic vision, LeCun believes we are much further from that scenario and that there’s no need to be so alarmist.
Isn’t it logical to be a little more extreme in our hypotheses, given that processing power is already far beyond what humans can audit?
Yes, I think it’s reasonable to have those concerns. The processing these systems are capable of is already beyond the scope of what a human could directly audit, and it’s difficult to foresee all the consequences. That’s why it’s important to continue researching and discussing AI alignment and safety, even if some people think we’re far from facing those risks. It’s better to be prepared for a scenario in which things could spiral out of control, even if we aren’t that close to it today.
Could you recommend some books for those interested in these topics?
One book I highly recommend is Capitalismo de plataformas by Nick Srnicek, which explains how big tech companies use data to generate wealth. It’s published by Caja Negra, an Argentine publishing house that specializes in works on critical thinking, contemporary philosophy, and technology. Another very interesting book is Dealers of Lightning, about Xerox PARC, a laboratory where many of the technologies we use today—such as the mouse and graphical user interfaces—were developed. And if you’re interested in something more literary, I recommend reading Ricardo Piglia. He has a book called La forma inicial, which compiles interviews in which he discusses literature and technology. This book is published by Eterna Cadencia, another Argentine publishing house that publishes both fiction and essays, with a carefully curated focus on contemporary literature.


